One Laptop, Two Ports, Real Wires: A USB-RS232-RS485 Loopback for Modbus Testing

Overview

At One-Way Automation we develop OPC UA Modbus Server, which connects Modbus devices to OPC UA clients. Much of its testing can be done with software alone, using Modbus slave simulators and virtual COM port pairs. But virtual ports behave like perfect wires: no real UART timing, no RS232 to RS485 conversion, no half-duplex direction switching and no USB adapter drivers with their own quirks. To cover those cases too, we built this setup with real converters and real cables, so the server can be tested the way it runs in the field: over genuine RS232 and RS485 links.

This bench setup turns a laptop's two USB ports into an RS232 port and an RS485 port that talk to each other. Use it to test serial and Modbus RTU software, such as master/slave simulators, gateways and protocol drivers, without any field device.

Data written to the RS232 port goes out as RS232 and is converted to RS485, then arrives on the RS485 port. Data flows the other way just as well.

Note: the same converters also connect the laptop to real devices, on either port type. Plug the Benfei adapter into an RS232 device, or wire the DTech 5019 to an RS485 bus. The Benfei and the DT-9000 together also let an RS232 port talk to RS485 devices. So once the software has passed on the loopback, the same kit tests it against real Modbus RTU devices.

What you need

#DeviceManufacturer / modelChipRole
1USB to RS232 converterBenfeiProlific PL2303GTRS232 port (COM5 in this setup)
2RS232 to RS485 converterDTech DT-9000none (passive, port-powered)Converts between RS232 and RS485
3USB to RS485 converterDTech 5019 (2nd)Silicon Labs CP2102NRS485 port (COM6 in this setup)

Cabling:

  • RS232 link: no cable. The Benfei's male DB9 plugs straight into the DT-9000's female DB9.
  • RS485 link: two DB9 to terminal block adapters (one comes with each DTech converter) plus three wires.

Windows assigns the COM port numbers, so yours may differ from COM5 and COM6 used throughout this post.

Setup overview

Laptop (Windows 11) 2 USB ports USB-1 → COM5 USB-2 → COM6 USB cable USB cable Benfei USB → RS232 PL2303GT COM5 · RS232 DB9 male → female DTech DT-9000 RS232 → RS485 port-powered T/R+ T/R- GND VCC +5V T/R+ T/R- RXD+ RXD- GND T/R+ T/R- GND not connected not connected DTech 5019 (2nd) USB → RS485 CP2102N COM6 · RS485 RS232 · plugged in directly RS485 · DB9 → terminal block adapters + 3 wires (2-wire, half-duplex) RS485 wires: red = T/R+ · blue = T/R- · black = GND · grey terminals = not connected
The complete chain: laptop USB-1 → Benfei → DT-9000 → terminal block adapters → DTech 5019 → laptop USB-2.

Wiring

RS232 link: Benfei to DT-9000

The Benfei's male DB9 plugs straight into the DT-9000's female DB9. No cable, gender changer or wires are needed. Tighten the two thumb screws so the connector can't work loose.

When the connectors are plugged together, each pin meets the hole with the same number. The numbers are also usually moulded, very small, into the plastic next to the pins.

Benfei pinDT-9000 pinSignalUsed for
33TXDData from the laptop into the DT-9000
22RXDData from the DT-9000 back to the laptop
55GNDSignal ground
44DTRPowers the DT-9000
77RTSPowers the DT-9000

Pins 1, 6, 8 and 9 are connected too, because all nine pins mate, but they aren't used.

  • The DT-9000 is port-powered: it has no power supply of its own and takes its power from the DTR and RTS lines (pins 4 and 7). DTR and RTS must be enabled in the software that opens the RS232 port. The test script below does this. At the tested baud rates (up to 115200) it needs no external power. If it ever does, supply 5 V to the VCC terminal of its RS485 adapter.
  • Don't use a null-modem adapter in this link. It swaps pins 2 and 3, and then no data gets through.

RS485 link: DT-9000 to DTech 5019

The RS485 ends of the DT-9000 and the 5019 are both male DB9s, so they aren't connected to each other directly. Instead, each one has a DB9 to terminal block adapter plugged on. It's also sold as a "DB9 breakout" or "DB9 screw-terminal adapter", and one comes with each DTech converter. The adapter brings the RS485 signals out to labelled screw terminals (Phoenix-type terminal blocks), and ordinary wires run between the terminals of the two adapters.

This is 2-wire half-duplex. Only three wires are used, from terminal to terminal, like to like:

DT-9000 adapter terminalWire colourDTech 5019 adapter terminal
T/R+ (A, D+)redT/R+
T/R- (B, D-)blueT/R-
GNDblackGND
  • The DT-9000's terminal block has 4 terminals: T/R+, T/R-, GND and VCC (+5 V). VCC is an optional external 5 V power input. It's left empty here because the DT-9000 is powered through the DTR and RTS lines on its RS232 side. If you ever need external power, this is where the 5 V goes.
  • Every other terminal stays empty. That includes the 5019's RXD+ and RXD-, which are for 4-wire RS422/RS485.
  • Tighten each screw on the bare copper, not on the wire's insulation, and tug each wire gently to check it's held.
  • If no data gets through, swap T/R+ and T/R-. Manufacturers don't agree on which letter (A or B) means +, and swapping them does no harm.
  • No termination resistor is needed. The cable is short (much shorter than 10 m), so reflections don't matter. Add 120 Ω across T/R+ and T/R- only if you lengthen the cable or see CRC or framing errors.
  • The GND wire is optional here. Both converters already share the laptop's USB ground. Connect it anyway as good practice. In real installations where the devices have separate power supplies, it is required.
  • Direction switching is automatic: both DTech devices switch between sending and receiving by themselves, so the software never has to toggle RTS.

Drivers (Windows 11)

AdapterDriverWhere to get it
Benfei (PL2303GT)ProlificInstalled automatically by Windows Update
DTech 5019 (CP2102N)Silicon Labs CP210x Universal Windows Driver, v11.6.0.420silabs.com: USB to UART bridge VCP drivers

Known issue: after the DTech 5019 is plugged in, it may show up in Device Manager as "CP2102N USB to UART Bridge Controller" with a yellow exclamation mark (error code 28: drivers not installed). The adapter doesn't need any setup. Windows just has no driver for it, and the driver on DTech's download page may be for a different chip.

To fix it:

  1. Download and extract the Silicon Labs CP210x Universal Windows Driver.
  2. In Device Manager, right-click the device → Update driver → Browse my computer → select the extracted folder. Alternatively, in an admin terminal, run pnputil /add-driver <folder>\silabser.inf /install.
  3. The device should then appear under Ports (COM & LPT) as "Silicon Labs CP210x USB to UART Bridge (COM6)".

To check the ports from PowerShell:

Get-PnpDevice -PresentOnly -Class Ports | Format-Table Status, FriendlyName

Serial port settings

  • Use the same settings on both ports, for example 9600 8N1 or 115200 8N1.
  • Turn flow control off. Only TX, RX and GND cross the RS485 link, so the RTS/CTS and DTR/DSR handshake lines have no effect on the other side.
  • The link is half-duplex, so only one side may send at a time.
  • Data sent on one port does not come back on the same port (no echo was observed).

Testing

1. Raw loopback

Send a string on one port and read it back on the other:

DirectionSentReceivedEcho
COM5 → COM6HELLO_FROM_RS232HELLO_FROM_RS232none
COM6 → COM5HELLO_FROM_RS485HELLO_FROM_RS485none

For a manual check, open both ports in two terminal programs (PuTTY, RealTerm or Termite) with the same settings and type into either one.

2. Modbus RTU test script

The script modbus_test.py runs a Modbus RTU slave on one port (in a background thread) and a master on the other. It then swaps them, so both the RS232 and RS485 sides are tested as master. It contains its own small Modbus RTU implementation, so the only dependency is pyserial:

pip install pyserial

Usage:

python modbus_test.py                                   # both directions, 9600 8N1, 100 stress cycles
python modbus_test.py --baud 115200 --cycles 1000
python modbus_test.py --baud 19200 --parity E
python modbus_test.py --direction 232-master            # or 485-master
python modbus_test.py --rs232 COM5 --rs485 COM6 --unit 17 --timeout 0.5
OptionDefaultMeaning
--rs232COM5RS232-side port
--rs485COM6RS485-side port
--baud9600Baud rate
--parityNParity: N, E or O. Data bits are 8 and stop bits are 1.
--unit1Slave unit ID
--timeout1.0Master response timeout, in seconds
--cycles100Number of random write/read-back stress cycles
--directionbothboth, 232-master or 485-master

The script exits with code 0 if every test passes and 1 otherwise. If the slave doesn't answer the first request at all, it reports "no response from slave at all" and skips the remaining tests, so a broken link fails in about 2 s instead of timing out on every request.

For a quick check after rewiring, run python modbus_test.py --baud 115200 --cycles 20 --timeout 0.3. It takes a few seconds.

What it tests:

TestWhat it checks
Function code 06: write one registerMaster writes, slave echoes the request back
Function code 03: read it backValue matches
Function code 16: write 10 registersRandom values are accepted
Function code 03: read back 10 registersValues match
Function code 03: read 125 registersLargest standard response frame (255 bytes)
Function code 05: write coil ONCoil write
Function code 01: read coilsThe written coil is set and the neighbouring coil is not
Error response 02Reading an address that doesn't exist returns "illegal data address"
Error response 01Sending an unsupported function code returns "illegal function"
Wrong unit IDThe slave stays silent and the master times out
StressN random write/read-back cycles; reports errors and average/maximum round-trip time
Show the full script: modbus_test.py
#!/usr/bin/env python3
"""Modbus RTU loopback test between two local serial ports.

Runs a Modbus RTU slave on one port (background thread) and a master on the
other, exercises the common function codes and verifies the results.
By default the test runs twice: RS232 side as master, then RS485 side as master.

Bench wiring:
    COM5 = RS232  (Benfei USB-RS232 -> Dtech RS232->RS485 converter)
    COM6 = RS485  (DTech 5019 USB-RS485, CP2102N)

Requires only pyserial:  pip install pyserial

Examples:
    python modbus_test.py
    python modbus_test.py --baud 19200 --parity E --cycles 500
    python modbus_test.py --direction 232-master
"""
import argparse
import random
import struct
import sys
import threading
import time

import serial


# ---------------------------------------------------------------- framing

def crc16(data: bytes) -> int:
    crc = 0xFFFF
    for b in data:
        crc ^= b
        for _ in range(8):
            crc = (crc >> 1) ^ 0xA001 if crc & 1 else crc >> 1
    return crc


def add_crc(frame: bytes) -> bytes:
    return frame + struct.pack("<H", crc16(frame))


def crc_ok(frame: bytes) -> bool:
    return len(frame) >= 4 and crc16(frame[:-2]) == struct.unpack("<H", frame[-2:])[0]


def read_exact(ser, n, deadline):
    buf = bytearray()
    while len(buf) < n and time.perf_counter() < deadline:
        buf += ser.read(n - len(buf))
    return bytes(buf)


def read_until_idle(ser, deadline):
    buf = bytearray()
    while time.perf_counter() < deadline:
        chunk = ser.read(256)
        if not chunk:
            break
        buf += chunk
    return bytes(buf)


def open_port(name, baud, parity):
    ser = serial.Serial(name, baud, bytesize=8, parity=parity, stopbits=1, timeout=0.05)
    ser.dtr = True  # DTR/RTS may power a port-powered RS232->RS485 converter
    ser.rts = True
    time.sleep(0.2)
    ser.reset_input_buffer()
    return ser


class ModbusException(Exception):
    NAMES = {1: "ILLEGAL FUNCTION", 2: "ILLEGAL DATA ADDRESS", 3: "ILLEGAL DATA VALUE"}

    def __init__(self, code):
        super().__init__(f"exception {code} ({self.NAMES.get(code, '?')})")
        self.code = code


# ---------------------------------------------------------------- slave

class Slave(threading.Thread):
    def __init__(self, ser, unit, size=200):
        super().__init__(daemon=True)
        self.ser, self.unit = ser, unit
        self.regs = [0] * size
        self.coils = [False] * size
        self.stop_event = threading.Event()
        self.crc_errors = 0

    def run(self):
        while not self.stop_event.is_set():
            first = self.ser.read(1)
            if not first:
                continue
            deadline = time.perf_counter() + 0.5
            frame = first + read_exact(self.ser, 1, deadline)
            if len(frame) < 2:
                continue
            fc = frame[1]
            if fc in (1, 2, 3, 4, 5, 6):
                frame += read_exact(self.ser, 6, deadline)
            elif fc in (15, 16):
                frame += read_exact(self.ser, 5, deadline)
                if len(frame) == 7:
                    frame += read_exact(self.ser, frame[6] + 2, deadline)
            else:
                frame += read_until_idle(self.ser, deadline)
            if not crc_ok(frame):
                self.crc_errors += 1
                self.ser.reset_input_buffer()
                continue
            if frame[0] != self.unit:
                continue  # addressed to another unit: stay silent
            self.ser.write(add_crc(bytes([self.unit]) + self.handle(frame[1:-2])))

    def _check(self, table, addr, qty):
        if qty < 1 or addr + qty > len(table):
            raise ModbusException(2)

    def handle(self, pdu):
        fc, data = pdu[0], pdu[1:]
        try:
            if fc == 1:
                addr, qty = struct.unpack(">HH", data[:4])
                self._check(self.coils, addr, qty)
                out = bytearray((qty + 7) // 8)
                for i, bit in enumerate(self.coils[addr:addr + qty]):
                    if bit:
                        out[i // 8] |= 1 << (i % 8)
                return bytes([fc, len(out)]) + out
            if fc == 3:
                addr, qty = struct.unpack(">HH", data[:4])
                if qty > 125:
                    raise ModbusException(3)
                self._check(self.regs, addr, qty)
                return bytes([fc, qty * 2]) + struct.pack(f">{qty}H", *self.regs[addr:addr + qty])
            if fc == 5:
                addr, val = struct.unpack(">HH", data[:4])
                if val not in (0xFF00, 0x0000):
                    raise ModbusException(3)
                self._check(self.coils, addr, 1)
                self.coils[addr] = val == 0xFF00
                return pdu
            if fc == 6:
                addr, val = struct.unpack(">HH", data[:4])
                self._check(self.regs, addr, 1)
                self.regs[addr] = val
                return pdu
            if fc == 16:
                addr, qty, count = struct.unpack(">HHB", data[:5])
                if count != qty * 2:
                    raise ModbusException(3)
                self._check(self.regs, addr, qty)
                self.regs[addr:addr + qty] = struct.unpack(f">{qty}H", data[5:5 + count])
                return pdu[:5]
            raise ModbusException(1)
        except ModbusException as e:
            return bytes([fc | 0x80, e.code])


# ---------------------------------------------------------------- master

class Master:
    def __init__(self, ser, unit, timeout):
        self.ser, self.unit, self.timeout = ser, unit, timeout
        self.last_rtt = 0.0

    def request(self, pdu, unit=None):
        unit = self.unit if unit is None else unit
        self.ser.reset_input_buffer()
        start = time.perf_counter()
        self.ser.write(add_crc(bytes([unit]) + pdu))
        deadline = start + self.timeout
        frame = read_exact(self.ser, 2, deadline)
        if len(frame) < 2:
            raise TimeoutError("no response")
        fc = frame[1]
        if fc & 0x80:
            frame += read_exact(self.ser, 3, deadline)
        elif fc in (1, 2, 3, 4):
            frame += read_exact(self.ser, 1, deadline)
            if len(frame) == 3:
                frame += read_exact(self.ser, frame[2] + 2, deadline)
        else:
            frame += read_exact(self.ser, 6, deadline)
        self.last_rtt = time.perf_counter() - start
        if not crc_ok(frame):
            raise IOError(f"bad/short response: {frame.hex(' ')}")
        if frame[0] != unit:
            raise IOError(f"response from unit {frame[0]}, expected {unit}")
        if fc & 0x80:
            raise ModbusException(frame[2])
        return frame[1:-2]

    def read_holding(self, addr, qty):
        resp = self.request(struct.pack(">BHH", 3, addr, qty))
        return list(struct.unpack(f">{qty}H", resp[2:2 + qty * 2]))

    def write_register(self, addr, val):
        return self.request(struct.pack(">BHH", 6, addr, val))

    def write_registers(self, addr, values):
        pdu = struct.pack(f">BHHB{len(values)}H", 16, addr, len(values), len(values) * 2, *values)
        return self.request(pdu)

    def read_coils(self, addr, qty):
        resp = self.request(struct.pack(">BHH", 1, addr, qty))
        return [bool(resp[2 + i // 8] >> (i % 8) & 1) for i in range(qty)]

    def write_coil(self, addr, on):
        return self.request(struct.pack(">BHH", 5, addr, 0xFF00 if on else 0))


# ---------------------------------------------------------------- tests

def expect_exception(fn, code):
    try:
        fn()
    except ModbusException as e:
        assert e.code == code, f"got exception {e.code}, expected {code}"
        return
    raise AssertionError(f"no exception, expected {code}")


def expect_timeout(fn):
    try:
        fn()
    except TimeoutError:
        return
    raise AssertionError("got a response, expected silence")


def run_tests(m: Master, cycles):
    vals = [random.randint(0, 0xFFFF) for _ in range(10)]
    tests = [
        ("FC06 write single register",
         lambda: m.write_register(0, 0x1234)),
        ("FC03 read back single register",
         lambda: (lambda r: None if r == [0x1234] else _fail(r))(m.read_holding(0, 1))),
        ("FC16 write 10 registers",
         lambda: m.write_registers(10, vals)),
        ("FC03 read back 10 registers",
         lambda: (lambda r: None if r == vals else _fail(r))(m.read_holding(10, 10))),
        ("FC03 read 125 registers (max frame)",
         lambda: (lambda r: None if len(r) == 125 else _fail(len(r)))(m.read_holding(0, 125))),
        ("FC05 write coil ON",
         lambda: m.write_coil(3, True)),
        ("FC01 read coils",
         lambda: (lambda r: None if r[3] and not r[2] else _fail(r))(m.read_coils(0, 8))),
        ("Exception 02: illegal address",
         lambda: expect_exception(lambda: m.read_holding(500, 1), 2)),
        ("Exception 01: illegal function",
         lambda: expect_exception(lambda: m.request(bytes([0x41])), 1)),
        ("Wrong unit id -> no response",
         lambda: expect_timeout(lambda: m.request(struct.pack(">BHH", 3, 0, 1), unit=m.unit + 1))),
    ]

    # fail fast: if the slave doesn't answer at all, the remaining tests would only time out
    try:
        m.read_holding(0, 1)
    except TimeoutError:
        print("  FAIL  no response from slave at all - check wiring/power; remaining tests skipped")
        return 0, len(tests) + (1 if cycles else 0)

    passed = 0
    for name, fn in tests:
        try:
            start = time.perf_counter()
            fn()
            print(f"  PASS  {name:<40} {(time.perf_counter() - start) * 1000:7.1f} ms")
            passed += 1
        except Exception as e:
            print(f"  FAIL  {name:<40} {e}")

    # stress: random write/read-back cycles
    errors, rtts = 0, []
    for _ in range(cycles):
        addr = random.randint(0, 190)
        data = [random.randint(0, 0xFFFF) for _ in range(random.randint(1, 10))]
        try:
            m.write_registers(addr, data)
            rtts.append(m.last_rtt)
            if m.read_holding(addr, len(data)) != data:
                raise AssertionError("mismatch")
            rtts.append(m.last_rtt)
        except Exception:
            errors += 1
    if cycles:
        ok = errors == 0
        passed += ok
        avg = sum(rtts) / len(rtts) * 1000 if rtts else 0
        mx = max(rtts) * 1000 if rtts else 0
        print(f"  {'PASS' if ok else 'FAIL'}  {cycles} write/read-back cycles, {errors} errors"
              f"   rtt avg {avg:.1f} ms, max {mx:.1f} ms")
    return passed, len(tests) + (1 if cycles else 0)


def _fail(got):
    raise AssertionError(f"unexpected value: {got}")


def run_direction(label, master_port, slave_port, args):
    print(f"\n=== {label}: master on {master_port}, slave (unit {args.unit}) on {slave_port} ===")
    ms = open_port(master_port, args.baud, args.parity)
    ss = open_port(slave_port, args.baud, args.parity)
    slave = Slave(ss, args.unit)
    slave.start()
    try:
        passed, total = run_tests(Master(ms, args.unit, args.timeout), args.cycles)
    finally:
        slave.stop_event.set()
        slave.join(1)
        ms.close()
        ss.close()
    if slave.crc_errors:
        print(f"  slave saw {slave.crc_errors} frame(s) with bad CRC")
    print(f"  --> {passed}/{total} passed")
    return passed == total


def main():
    p = argparse.ArgumentParser(description="Modbus RTU loopback test between two serial ports")
    p.add_argument("--rs232", default="COM5", help="RS232-side port (default COM5)")
    p.add_argument("--rs485", default="COM6", help="RS485-side port (default COM6)")
    p.add_argument("--baud", type=int, default=9600)
    p.add_argument("--parity", choices="NEO", default="N")
    p.add_argument("--unit", type=int, default=1, help="slave unit id (default 1)")
    p.add_argument("--timeout", type=float, default=1.0, help="response timeout, s")
    p.add_argument("--cycles", type=int, default=100, help="stress write/read cycles")
    p.add_argument("--direction", choices=["both", "232-master", "485-master"], default="both")
    args = p.parse_args()

    print(f"Modbus RTU loopback test, {args.baud} 8{args.parity}1")
    ok = True
    if args.direction in ("both", "232-master"):
        ok &= run_direction("RS232 master -> RS485 slave", args.rs232, args.rs485, args)
    if args.direction in ("both", "485-master"):
        ok &= run_direction("RS485 master -> RS232 slave", args.rs485, args.rs232, args)
    print("\nRESULT:", "ALL PASSED" if ok else "FAILURES")
    sys.exit(0 if ok else 1)


if __name__ == "__main__":
    main()

Results

Both directions, all tests passed with the setup as described above. The full run at both baud rates takes about 40 s.

9600 8N1 (100 cycles)115200 8N1 (1000 cycles)
Single-register write or read~15 ms~4 ms
Write/read 10 registers~31–47 ms~6 ms
Read 125 registers (255-byte response)~280 ms~27 ms
Stress round trip, average / maximum31 / 47 ms5.0 / 6.7 ms
Errors00

Notes:

  • At 115200, the ~4 ms minimum round trip is mostly USB delay. A short request and response only take about 1.4 ms to send at that speed; the rest comes from how the PL2303GT and CP2102N chips batch data.
  • The unsupported-function test takes ~104 ms because of how the test slave works. For an unknown function code it waits for 100 ms of silence to be sure the frame has ended before replying.
  • The wrong-unit-ID test always takes the full timeout (~1 s), which is expected.
  • The DT-9000 ran on port power alone at 115200 with no errors.

Troubleshooting

SymptomLikely cause and fix
Yellow exclamation mark on "CP2102N USB to UART Bridge Controller"The CP210x driver is missing. Install the Silicon Labs driver (see Drivers).
Data arrives on the RS485 port but nothing comes back to the RS232 port (every Modbus request gets no response)Seen once while setting up this bench, and gone after reconnecting. Make sure the Benfei is pushed fully into the DT-9000 and its screws are tight, check that DTR and RTS are on (they power the DT-9000), and check that the RS485 wires are firmly clamped.
Nothing received in either directionT/R+ and T/R- are swapped (swap them), a null-modem adapter is in the RS232 link, or an RS485 wire has come loose from its terminal
Intermittent errors or lost bytesA loose connection. Tighten the DB9 thumb screws and the terminal screws.
Works at low baud rates but fails at high onesThe DT-9000 is short of power. Make sure DTR and RTS are on, or supply 5 V to the VCC terminal of the DT-9000 adapter (and connect the supply ground to its GND). Also check the cable length and add 120 Ω termination if needed.
Random 0x00/0xFF bytes arrive while the line is idleThe bus lacks bias resistors. Enable the converter's bias/termination switch, or add ~680 Ω from T/R+ to +5 V and from T/R- to GND.
Your own transmitted data comes back on the sending portThe converter echoes what it sends. Have the software discard it. (Not observed with this setup.)
"Access denied" when opening a portAnother program (a terminal or simulator) already has the port open

Idako version 4.3.2 has been released

Application Health metrics in Prometheus format

We would like to inform you that a new version 4.3.2 of the application has been released. It has a new feature added: providing application health metrics via endpoint /health/?format=prometheus, which allows to integrate it with well known application health monitoring and alerting platforms such as NetData and Grafana. Now you can deploy either NetData or Grafana or both and get email notifications when unexpected behaviour of the application is detected:

  • Idako instance is not running,
  • it is disconnected from some OPC UA Server,
  • variables stop being updated,
  • connection with the destination time-series database is lost,
  • local buffer reaches its maximum size limit.

Combined with High Availability feature that was added in version 4.2.0, health monitoring increases relailability of Idako, making sure that no data is lost.
More details about monitoring Idako health can be found on these blog posts:

Full history of changes can be accessed at Release Notes page

Monitoring Idako Application Health with NetData

Getting started · monitoring

When you're collecting and logging critical industrial data, losing any of it usually isn't an option — which means you need to know, 24/7, that the application itself is running smoothly, and to find out immediately the moment something isn't. Idako 4.3.2 added exactly that: a comprehensive set of health metrics exposed through the /health endpoint in Prometheus format, the industry standard for monitoring — letting you plug in a monitoring agent to watch every component and get notified the instant something goes wrong.

This guide walks through wiring that endpoint into NetData: two of its built-in collectors read /health — one that works today with zero setup, another that unlocks per-component and per-server detail once you're on Idako 4.3.2 — and NetData's own alerting emails you the moment something breaks. Nothing new to run: if a NetData agent is already watching this host, this uses it as-is.

about 15 minutes Idako 4.3.2 or later, for full metrics a NetData agent already installed network access to your Idako instance's health port outbound email already working on the NetData host
1

Get the config files

Download the ready-to-copy config files and unzip them as a folder named idako-netdata — four small files that plug into a NetData install you already have, nothing built from scratch. Two are collector job files (where to look), two are matching alert rule files (what counts as a problem):

idako-netdata/ ├── README.md ├── go.d/ │ ├── httpcheck.conf │ └── prometheus.conf └── health.d/ ├── idako-httpcheck.conf └── idako-prometheus.conf
Two collectors, checking two different things. httpcheck (step 2) works against /health exactly as it is today, on any Idako version, and is what reliably catches the instance being completely unreachable. The prometheus collector (step 3) needs Idako 4.3.2's /health?format=prometheus and unlocks per-component status and per-server detail. Run both side by side — one isn't a replacement for the other.
2

Point httpcheck at Idako

Open go.d/httpcheck.conf — it polls /health with a plain HTTP request and checks for a 200 response containing "status":"OK". The only thing to adjust is the target address:

go.d/httpcheck.conf
update_every: 5

jobs:
  - name: idako_local
    url: http://idako-host:4880/health
    status_accepted: [200]
    response_match: '"status"\s*:\s*"OK"'
    timeout: 3

Replace idako-host and 4880 with your Idako instance's actual host and port. The job's name matters too: it becomes the chart family NetData groups this check under, and it's what the alert rules in step 4 match against by the idako_ prefix — keep that prefix if you rename it.

3

Add richer metrics via Prometheus

Idako 4.3.2 also exposes /health in Prometheus's own text format, via a query parameter — the same format the Idako + Grafana guide reads with a dedicated Prometheus server, read here instead by NetData's own prometheus collector. Where httpcheck only tells you up or down, this charts every subsystem individually: the OPC UA collector engine, the local buffer, the tsdb connection, and each configured server by name.

go.d/prometheus.conf
update_every: 10

jobs:
  - name: idako_local
    url: http://idako-host:4880/health?format=prometheus
    app: idako
    expected_prefix: idako_
    max_time_series: 500

Same host/port substitution as step 2. app: idako groups the resulting charts under a predictable name in the dashboard; expected_prefix is a guard rail against accidentally scraping something that isn't Idako.

Confirm the exact chart names once, after step 6. NetData derives each chart's internal name from the metric name and this app: setting. The alert rules in the next step already use the documented pattern (prometheus.idako.<metric>), but it's worth a one-time check once data is flowing: curl -s http://localhost:19999/api/v1/contexts | grep idako.
4

Install the alert rules

Two files, one per collector from steps 2–3, written as templates — a template attaches to every matching chart automatically, so adding a second Idako instance later (see "Monitoring more than one instance") needs no changes here.

Reachability — pairs with httpcheck

health.d/idako-httpcheck.conf
template: idako_health_unreachable
      on: httpcheck.status
 families: idako_*
   lookup: average -1m unaligned percentage of success
    units: %
    every: 10s
     warn: $this < 100
     crit: $this < 50
    delay: down 30s multiplier 1.5 max 2m
     info: percentage of /health checks that succeeded (HTTP 200 + status:OK) in the last minute
       to: sysadmin

template: idako_health_response_slow
      on: httpcheck.response_time
 families: idako_*
   lookup: average -1m unaligned
    units: ms
    every: 10s
     warn: $this > 2000
     crit: $this > 5000
    delay: down 1m multiplier 1.5 max 5m
     info: average response time of Idako's /health endpoint over the last minute
       to: sysadmin

families: idako_* scopes both templates to job names starting with idako_, so they won't fire on unrelated httpcheck jobs running on the same agent.

Component health — pairs with the Prometheus collector

health.d/idako-prometheus.conf
template: idako_up_prom
      on: prometheus.idako.idako_up
   lookup: average -2m unaligned
    units: ratio
    every: 10s
     warn: $this < 1
     crit: $this == 0
    delay: down 30s multiplier 1.5 max 2m
     info: Idako reports overall status OK
       to: sysadmin

template: idako_collector_up_prom
      on: prometheus.idako.idako_collector_up
   lookup: average -1m unaligned
    units: ratio
    every: 15s
     warn: $this < 1
    delay: down 30s multiplier 1.5 max 2m
     info: Idako's OPC UA collector engine is not running
       to: sysadmin

template: idako_collector_disconnected_servers_prom
      on: prometheus.idako.idako_collector_disconnected_servers
   lookup: min -1m unaligned
    units: servers
    every: 30s
     warn: $this > 0
    delay: down 30s multiplier 1.5 max 2m
     info: one or more configured, active OPC UA servers are disconnected
       to: sysadmin

template: idako_collector_server_down_prom
      on: prometheus.idako.idako_collector_server_up
   lookup: min -1m unaligned foreach *
    units: ratio
    every: 30s
     warn: $this < 1
    delay: down 30s multiplier 1.5 max 2m
     info: this OPC UA server connection is not OK
       to: sysadmin

template: idako_collector_bad_variables_prom
      on: prometheus.idako.idako_collector_bad_variables
   lookup: average -1m unaligned
    units: variables
    every: 30s
     warn: $this > 0
     crit: $this > 100
    delay: down 1m multiplier 1.5 max 5m
     info: variables reporting bad quality, summed across the whole fleet
       to: sysadmin

template: idako_buffer_up_prom
      on: prometheus.idako.idako_buffer_up
   lookup: average -1m unaligned
    units: ratio
    every: 15s
     warn: $this < 1
    delay: down 30s multiplier 1.5 max 2m
     info: Idako's local buffer subsystem is not running
       to: sysadmin

template: idako_buffer_values_lost_prom
      on: prometheus.idako.idako_buffer_values_lost
   lookup: sum -5m unaligned incremental
    units: values
    every: 1m
     warn: $this > 0
    delay: down 1m multiplier 1.5 max 5m
     info: values could not be stored in the local buffer and were lost in the last 5 minutes
       to: sysadmin

template: idako_tsdb_down_prom
      on: prometheus.idako.idako_tsdb_up
   lookup: average -1m unaligned
    units: ratio
    every: 15s
     warn: $this < 1
    delay: down 30s multiplier 1.5 max 2m
     info: Idako's connection to the time-series database is not OK
       to: sysadmin

template: idako_tsdb_batches_failed_prom
      on: prometheus.idako.idako_tsdb_batches_failed
   lookup: sum -5m unaligned incremental
    units: batches
    every: 1m
     warn: $this > 0
    delay: down 1m multiplier 1.5 max 5m
     info: batches of values failed to forward to the tsdb in the last 5 minutes
       to: sysadmin
RuleFires whenSeverity
Idako unreachablehttpcheck stops getting HTTP 200 + status:OKwarning → critical
/health responding slowlyaverage response time > 2s (warn) / 5s (crit)warning / critical
Idako reports not OKidako_up is 0critical
Collector engine downidako_collector_up is 0warning
OPC UA server disconnectedidako_collector_server_up is 0 — one alert per serverwarning
Bad variables detectedidako_collector_bad_variables > 0 (warn) / > 100 (crit)warning / critical
Local buffer downidako_buffer_up is 0warning
Values lostidako_buffer_values_lost > 0 in the last 5mwarning
TSDB downidako_tsdb_up is 0warning
TSDB batch failuresidako_tsdb_batches_failed > 0 in the last 5mwarning
Why two separate "is it there" checks? httpcheck.status always writes a real 0 the moment a request fails outright — connection refused, timeout, wrong status code. idako_up_prom only evaluates once NetData has parsed a fresh Prometheus scrape; if the /health call fails completely, there's no idako_up sample to evaluate at all — a gap, not a 0 — and NetData's alarm engine doesn't reliably treat a gap as a failure. Keep both rules active: idako_health_unreachable catches "completely gone," idako_up_prom catches "up, but internally unhealthy."
5

Set the alert recipient

Every rule above ends in to: sysadmin — that's a role, not an address. NetData maps roles to real recipients in one file that (like Grafana's SMTP settings) isn't part of what you downloaded, since it holds where alerts actually go rather than what counts as a problem:

shell — Linux
cd /etc/netdata
sudo ./edit-config health_alarm_notify.conf

Set (or confirm) these values:

health_alarm_notify.conf
SEND_EMAIL="YES"
EMAIL_SENDER="alerts@example.com"
DEFAULT_RECIPIENT_EMAIL="you@example.com"

DEFAULT_RECIPIENT_EMAIL is where every to: sysadmin alarm above goes, since sysadmin is NetData's built-in default role. To send Idako's alerts to a different address than everything else on this host, set role_recipients_email[sysadmin]="you@example.com" instead — it overrides the default for just that one role.

Needs a working mail transport on this host. health_alarm_notify.conf hands the message to the system's own sendmail-compatible command to actually deliver it. If this host doesn't already send outbound mail, point it at a relay or install a local MTA first — that's a host-level prerequisite this file can't provide on its own.
On Windows, the same file lives at C:\Program Files\Netdata\etc\netdata\health_alarm_notify.conf — edit it from the bundled MSYS2 shell (C:\Program Files\Netdata\msys2.exe) as Administrator, since edit-config is a bash script and Program Files needs elevation to write to.
6

Turn it on

Three mechanical steps: confirm both collectors are enabled, copy the four files from step 1 into NetData's live config directory, and restart.

Enable the collectors

Both ship with default_run: yes, so this is usually a check, not a change:

shell — Linux
cd /etc/netdata
sudo ./edit-config go.d.conf
# confirm under modules:
#   httpcheck: yes
#   prometheus: yes
On Windows, run the equivalent from the bundled MSYS2 shell as Administrator: cd /etc/netdata && ./edit-config go.d.conf.

Copy the files in

shell — Linux
sudo cp go.d/httpcheck.conf     /etc/netdata/go.d/
sudo cp go.d/prometheus.conf    /etc/netdata/go.d/
sudo cp health.d/idako-httpcheck.conf   /etc/netdata/health.d/
sudo cp health.d/idako-prometheus.conf  /etc/netdata/health.d/
On Windows (PowerShell, as Administrator), Copy-Item the same four files into C:\Program Files\Netdata\etc\netdata\go.d\ and ...\health.d\ respectively.

Restart

shell — Linux
sudo systemctl restart netdata
On Windows, Restart-Service Netdata from an elevated PowerShell (or Services → Netdata → Restart).
7

Confirm it's working

Open http://localhost:19999 (or your NetData host's address) — NetData's own dashboard, no separate login to set up.

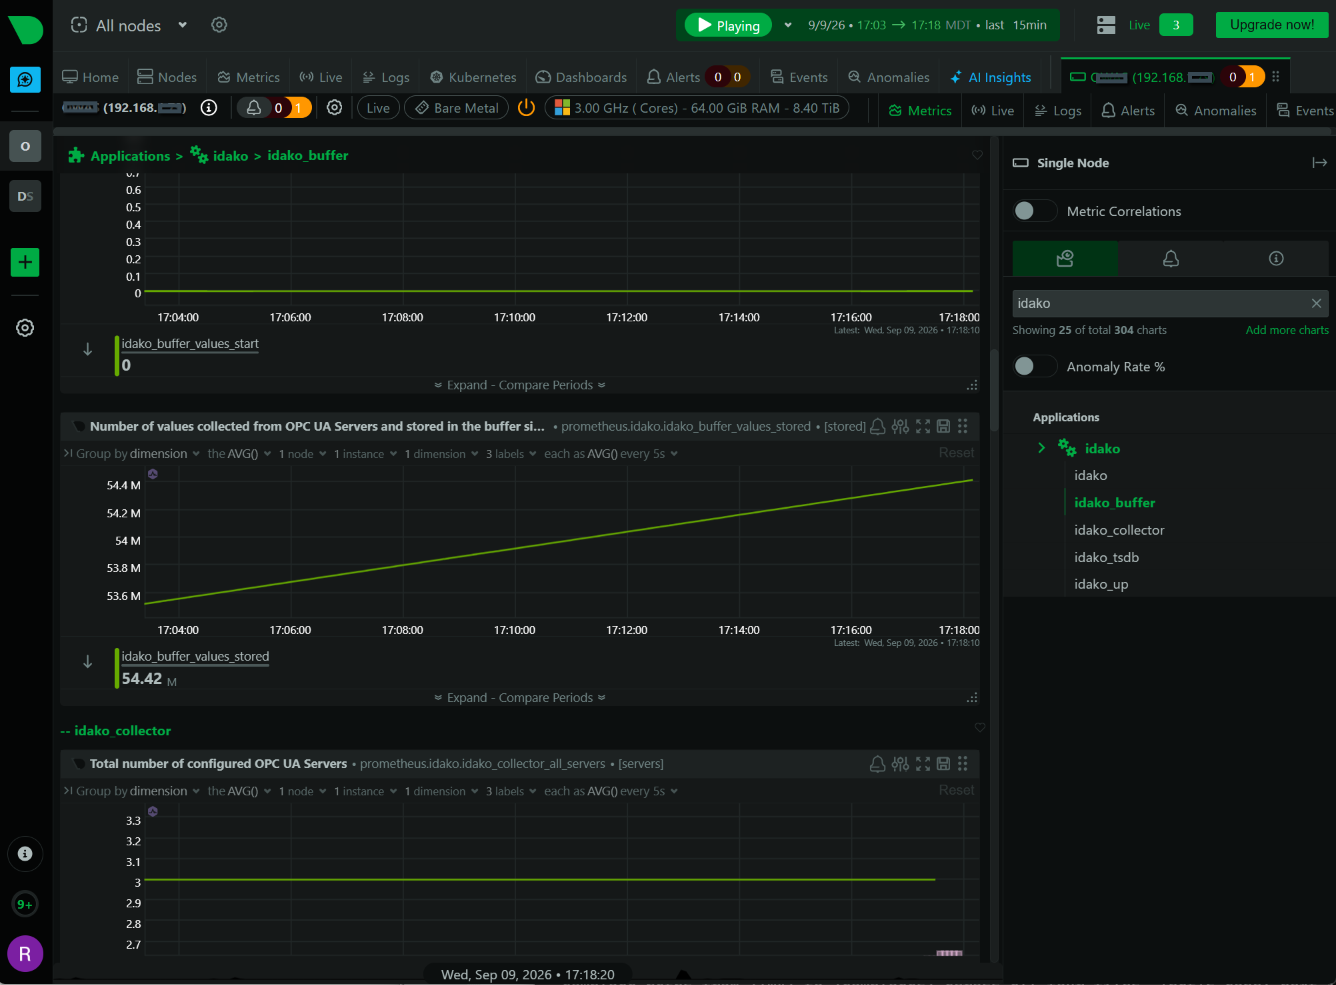
Look for an idako section in the left-hand menu. httpcheck's status and response-time charts should appear within a few seconds of restarting; the Prometheus-collector charts (per-component status, per-server detail) appear once step 3's job has scraped at least once. It should look something like this:

The idako section of NetData's dashboard: httpcheck status and response-time charts alongside per-component status for the collector engine, local buffer, and tsdb, plus a connection chart per configured OPC UA server.
NetData's idako section, running against a healthy instance.
You should see charts for httpcheck status and response time, plus — once the prometheus collector has run — separate status charts for the collector engine, local buffer, and tsdb, and one per configured OPC UA server. If the prometheus charts are missing, re-check the target directly with curl -s http://idako-host:4880/health?format=prometheus and revisit the one-time context-name check from step 3.
Beyond one instance

Monitoring more than one Idako instance

Add one more job to each collector file — nothing else changes, since every alert rule from step 4 is a template (or already scoped with families: idako_*) that automatically covers every matching job:

go.d/httpcheck.conf (excerpt)
  - name: idako_site_b
    url: https://idako-site-b.example.com/health
    status_accepted: [200]
    response_match: '"status"\s*:\s*"OK"'
    timeout: 3
go.d/prometheus.conf (excerpt)
  - name: idako_site_b
    url: https://idako-site-b.example.com/health?format=prometheus
    app: idako
    expected_prefix: idako_
    max_time_series: 500

Restart NetData to pick up the new jobs — unlike a health.d-only change, adding a job needs a full restart, not just reload-health.

Before you trust it

Verifying the alerts actually work

A clean restart only proves NetData accepted the config, not that a real notification gets delivered. Two checks worth doing once, right after setup:

  • Send a test notification — NetData ships a self-test for exactly this: sudo /usr/libexec/netdata/plugins.d/alarm-notify.sh test sends a real test message through every configured method, sysadmin included. Confirms step 5's settings actually deliver, before any real alarm depends on them.
  • Trigger a real one — stop Idako (or block the port) and wait a minute or two. idako_health_unreachable should move to warning, then critical, and an email should follow shortly after. Bring Idako back and you should get a second, "recovered" notification once it clears.
Notifications not arriving? Start with the self-test above, not the health.d files — if alarm-notify.sh test doesn't deliver either, it's a mail-transport problem on this host, not a config problem with the rules themselves.
Next steps

Where to go from here

Want fuller dashboards and PromQL-based alerting?The Idako + Grafana guide reads this same /health?format=prometheus endpoint with a dedicated Prometheus server and a Grafana dashboard — heavier to run, more powerful to query.
Detailed charts before every instance is on 4.3.2NetData's pandas collector can read the plain JSON /health body as a bridge — Linux-only in practice; confirm python.d.plugin and a Python 3 + pandas/requests environment before relying on it.
Route alerts to more than emailhealth_alarm_notify.conf supports Slack, PagerDuty, and a long list of other methods alongside email — same to: sysadmin roles, more delivery options per role.
See exactly what Idako reportsThe full field-by-field reference for /health, including every metric this guide's charts and alerts are built from.
This talks to Idako over plain HTTP on its health port — no credentials, and nothing new to install if a NetData agent is already watching this host.

Monitoring Idako Application Health with Grafana

Getting started · monitoring

When you're collecting and logging critical industrial data, losing any of it usually isn't an option — which means you need to know, 24/7, that the application itself is running smoothly, and to find out immediately the moment something isn't. Idako 4.3.2 added exactly that: a comprehensive set of health metrics exposed through the /health endpoint in Prometheus format, the industry standard for monitoring — letting you plug in a tool like Grafana to watch every component and get notified the instant something goes wrong.

This guide walks through a self-hosted monitoring stack you run in Docker: Prometheus scrapes that health data, Grafana turns it into a live dashboard — and emails you the moment something breaks. No cloud account, no agents to install on the Idako host itself.

about 25 minutes Idako 4.3.2 or later Docker & Docker Compose network access to your Idako instance's health port an SMTP relay, for email alerts
1

Get the project folder

Download the complete configuration and unzip it as a folder named idako-monitoring — everything below lives in that one folder, so the whole stack can be started, stopped, and moved as a unit. You'll adjust a handful of values inside it (your Idako host/port, SMTP details, alert recipient) over the next few steps; nothing needs to be built from scratch. Here's what's inside:

idako-monitoring/ ├── docker-compose.yml ├── .env-example ├── .gitignore ├── prometheus/ │ └── prometheus.yml └── grafana/ └── provisioning/ ├── datasources/ │ └── prometheus.yml ├── dashboards/ │ ├── dashboards.yml │ └── idako-overview.json └── alerting/ ├── contactpoints.yaml ├── policies.yaml └── rules.yaml
Note the missing .env. That file holds your real SMTP password and isn't included in the download — step 4 has you create it yourself from .env-example, and .gitignore (also from step 4) keeps it out of version control.
2

Point Prometheus at Idako

Open prometheus/prometheus.yml — it tells Prometheus what to scrape and how often, requesting Idako's health data in Prometheus format via a query parameter. The only thing to adjust is the target address:

prometheus/prometheus.yml
global:
  scrape_interval: 15s

scrape_configs:
  - job_name: idako
    metrics_path: /health
    params:
      format: [prometheus]
    static_configs:
      - targets: ["idako-host:4880"]

Replace idako-host and 4880 in targets with your Idako instance's actual host and port — that's the only edit this file needs.

Running Idako on the same machine as Docker? On Linux, use host.docker.internal only if your Docker version maps it (add extra_hosts: ["host.docker.internal:host-gateway"] under the prometheus service in step 5 if needed) — on Docker Desktop for Windows/Mac it works out of the box.
3

Provision the Grafana dashboard

Instead of clicking through Grafana's UI to add a data source and build panels by hand, three files already sitting in grafana/provisioning/ do it automatically, the same way every time you start the stack. Here's what each one does — none of them need editing.

Connects Grafana to Prometheus

grafana/provisioning/datasources/prometheus.yml
apiVersion: 1

datasources:
  - name: Prometheus
    uid: prometheus
    type: prometheus
    access: proxy
    url: http://prometheus:9090
    isDefault: true

http://prometheus:9090 works because Docker Compose puts both containers on the same network and lets them reach each other by service name — there's nothing to substitute here. The explicit uid: prometheus matters more than it looks: the dashboard panels below and the alert rules in step 4 both reference the datasource by this exact id, so pinning it here keeps everything pointed at the same place, rather than relying on whatever id Grafana would otherwise generate on its own.

Tells Grafana where to find dashboards

grafana/provisioning/dashboards/dashboards.yml
apiVersion: 1

providers:
  - name: Idako
    folder: Idako
    type: file
    updateIntervalSeconds: 30
    options:
      path: /etc/grafana/provisioning/dashboards

The dashboard itself

grafana/provisioning/dashboards/idako-overview.json — eleven panels covering every subsystem: instance, collector, local buffer, and tsdb status; connected/disconnected server counts; buffer backlog; tsdb batch failures; the buffer pipeline (collected/forwarded/balance); collection & forwarding rate; and variable quality (total/good/bad). Nothing to change here either, unless you want to customize it later:

grafana/provisioning/dashboards/idako-overview.json
{
  "title": "Idako Overview",
  "uid": "idako-overview",
  "schemaVersion": 39,
  "version": 4,
  "editable": true,
  "timezone": "browser",
  "time": { "from": "now-6h", "to": "now" },
  "refresh": "5s",
  "panels": [
    {
      "title": "Instance Status",
      "type": "stat",
      "gridPos": { "x": 0, "y": 0, "w": 4, "h": 6 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "up{job=\"idako\"}", "refId": "A" }],
      "fieldConfig": {
        "defaults": {
          "mappings": [{ "type": "value", "options": {
            "0": { "text": "DOWN", "color": "red" },
            "1": { "text": "OK", "color": "green" }
          }}],
          "thresholds": { "mode": "absolute", "steps": [
            { "color": "red", "value": null }, { "color": "green", "value": 1 }
          ]}
        }, "overrides": []
      },
      "options": { "reduceOptions": { "calcs": ["lastNotNull"] }, "colorMode": "background", "graphMode": "none" }
    },
    {
      "title": "Collector Status",
      "type": "stat",
      "gridPos": { "x": 4, "y": 0, "w": 4, "h": 6 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "idako_collector_up", "refId": "A" }],
      "fieldConfig": {
        "defaults": {
          "mappings": [{ "type": "value", "options": {
            "0": { "text": "DOWN", "color": "red" },
            "1": { "text": "OK", "color": "green" }
          }}],
          "thresholds": { "mode": "absolute", "steps": [
            { "color": "red", "value": null }, { "color": "green", "value": 1 }
          ]}
        }, "overrides": []
      },
      "options": { "reduceOptions": { "calcs": ["lastNotNull"] }, "colorMode": "background", "graphMode": "none" }
    },
    {
      "title": "Local Buffer Status",
      "type": "stat",
      "gridPos": { "x": 8, "y": 0, "w": 4, "h": 6 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "idako_buffer_up", "refId": "A" }],
      "fieldConfig": {
        "defaults": {
          "mappings": [{ "type": "value", "options": {
            "0": { "text": "DOWN", "color": "red" },
            "1": { "text": "OK", "color": "green" }
          }}],
          "thresholds": { "mode": "absolute", "steps": [
            { "color": "red", "value": null }, { "color": "green", "value": 1 }
          ]}
        }, "overrides": []
      },
      "options": { "reduceOptions": { "calcs": ["lastNotNull"] }, "colorMode": "background", "graphMode": "none" }
    },
    {
      "title": "TSDB Status",
      "type": "stat",
      "gridPos": { "x": 12, "y": 0, "w": 4, "h": 6 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "idako_tsdb_up", "refId": "A" }],
      "fieldConfig": {
        "defaults": {
          "mappings": [{ "type": "value", "options": {
            "0": { "text": "DOWN", "color": "red" },
            "1": { "text": "OK", "color": "green" }
          }}],
          "thresholds": { "mode": "absolute", "steps": [
            { "color": "red", "value": null }, { "color": "green", "value": 1 }
          ]}
        }, "overrides": []
      },
      "options": { "reduceOptions": { "calcs": ["lastNotNull"] }, "colorMode": "background", "graphMode": "none" }
    },
    {
      "title": "Connected Servers",
      "type": "stat",
      "gridPos": { "x": 16, "y": 0, "w": 4, "h": 6 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "idako_collector_connected_servers", "refId": "A" }],
      "fieldConfig": { "defaults": { "color": { "mode": "thresholds" },
        "thresholds": { "mode": "absolute", "steps": [{ "color": "blue", "value": null }] } }, "overrides": [] },
      "options": { "reduceOptions": { "calcs": ["lastNotNull"] }, "graphMode": "none" }
    },
    {
      "title": "Disconnected Servers",
      "type": "stat",
      "gridPos": { "x": 20, "y": 0, "w": 4, "h": 6 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "idako_collector_disconnected_servers", "refId": "A" }],
      "fieldConfig": { "defaults": { "color": { "mode": "thresholds" },
        "thresholds": { "mode": "absolute", "steps": [
          { "color": "green", "value": null }, { "color": "red", "value": 1 }
        ]} }, "overrides": [] },
      "options": { "reduceOptions": { "calcs": ["lastNotNull"] }, "graphMode": "none" }
    },
    {
      "title": "Buffer Backlog (values waiting to forward)",
      "type": "timeseries",
      "gridPos": { "x": 0, "y": 6, "w": 12, "h": 8 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "idako_buffer_values_balance", "refId": "A" }],
      "fieldConfig": { "defaults": { "custom": { "drawStyle": "line", "lineWidth": 2, "fillOpacity": 15 },
        "color": { "mode": "palette-classic" } }, "overrides": [] },
      "options": { "legend": { "displayMode": "list", "placement": "bottom" }, "tooltip": { "mode": "single" } }
    },
    {
      "title": "TSDB Batch Failures (cumulative)",
      "type": "timeseries",
      "gridPos": { "x": 12, "y": 6, "w": 12, "h": 8 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [{ "expr": "idako_tsdb_batches_failed", "refId": "A" }],
      "fieldConfig": { "defaults": { "custom": { "drawStyle": "line", "lineWidth": 2, "fillOpacity": 15 },
        "color": { "fixedColor": "red", "mode": "fixed" } }, "overrides": [] },
      "options": { "legend": { "displayMode": "list", "placement": "bottom" }, "tooltip": { "mode": "single" } }
    },
    {
      "title": "Buffer Pipeline (collected / forwarded / balance)",
      "type": "timeseries",
      "gridPos": { "x": 0, "y": 14, "w": 8, "h": 8 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [
        { "expr": "idako_buffer_values_stored", "legendFormat": "Collected", "refId": "A" },
        { "expr": "idako_buffer_values_forwarded", "legendFormat": "Forwarded", "refId": "B" },
        { "expr": "idako_buffer_values_balance", "legendFormat": "Balance", "refId": "C" }
      ],
      "fieldConfig": {
        "defaults": { "custom": { "drawStyle": "line", "lineWidth": 2, "fillOpacity": 10 },
          "color": { "mode": "palette-classic" } },
        "overrides": [
          { "matcher": { "id": "byName", "options": "Balance" },
            "properties": [{ "id": "color", "value": { "mode": "fixed", "fixedColor": "orange" } }] }
        ]
      },
      "options": { "legend": { "displayMode": "list", "placement": "bottom" }, "tooltip": { "mode": "multi" } }
    },
    {
      "title": "Collection & Forwarding Rate (values/sec)",
      "type": "timeseries",
      "gridPos": { "x": 8, "y": 14, "w": 8, "h": 8 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [
        { "expr": "idako_collector_rate", "legendFormat": "Collection rate", "refId": "A" },
        { "expr": "idako_tsdb_values_forwarded_rate", "legendFormat": "Forwarding rate", "refId": "B" }
      ],
      "fieldConfig": { "defaults": { "custom": { "drawStyle": "line", "lineWidth": 2, "fillOpacity": 10 },
        "color": { "mode": "palette-classic" }, "unit": "reqps" }, "overrides": [] },
      "options": { "legend": { "displayMode": "list", "placement": "bottom" }, "tooltip": { "mode": "multi" } }
    },
    {
      "title": "Variables by Quality (total / good / bad)",
      "type": "timeseries",
      "gridPos": { "x": 16, "y": 14, "w": 8, "h": 8 },
      "datasource": { "type": "prometheus", "uid": "prometheus" },
      "targets": [
        { "expr": "idako_collector_all_variables", "legendFormat": "Total", "refId": "A" },
        { "expr": "idako_collector_good_variables", "legendFormat": "Good", "refId": "B" },
        { "expr": "idako_collector_bad_variables", "legendFormat": "Bad", "refId": "C" }
      ],
      "fieldConfig": {
        "defaults": { "custom": { "drawStyle": "line", "lineWidth": 2, "fillOpacity": 10 },
          "color": { "mode": "palette-classic" } },
        "overrides": [
          { "matcher": { "id": "byName", "options": "Total" },
            "properties": [{ "id": "color", "value": { "mode": "fixed", "fixedColor": "blue" } }] },
          { "matcher": { "id": "byName", "options": "Good" },
            "properties": [{ "id": "color", "value": { "mode": "fixed", "fixedColor": "green" } }] },
          { "matcher": { "id": "byName", "options": "Bad" },
            "properties": [{ "id": "color", "value": { "mode": "fixed", "fixedColor": "red" } }] }
        ]
      },
      "options": { "legend": { "displayMode": "list", "placement": "bottom" }, "tooltip": { "mode": "multi" } }
    }
  ]
}
Multiple OPC UA servers? These panels use the fleet-wide counts, which need no changes as servers are added or removed. To chart a specific server by name, add a panel with idako_collector_server_up{server="Your Server Name"}.
4

Set up email alerts

Three pieces, provisioned the same way as the dashboard: where to send email from, who receives it, and what conditions trigger it.

SMTP credentials — the one file you actually create yourself

Grafana needs real SMTP relay details to send anything, and that includes a password — which is exactly why it isn't part of the download. .env-example is the safe-to-share template already sitting in your folder; .env is the real file you make from it:

.env-example
# Copy this file to .env before starting the stack:
#   cp .env-example .env
# Then fill in your real SMTP relay details below. .env is gitignored and
# stays local to this machine only — never commit real credentials to Git.

# Required for Grafana's email alerts to actually send. Use your
# organization's own SMTP relay, or a transactional email provider
# (SendGrid, Mailgun, Amazon SES, etc.)
GF_SMTP_ENABLED=true
GF_SMTP_HOST=smtp.example.com:587
GF_SMTP_USER=alerts@example.com
GF_SMTP_PASSWORD=your-smtp-password
GF_SMTP_FROM_ADDRESS=alerts@example.com
GF_SMTP_FROM_NAME=Idako Monitoring
shell
cp .env-example .env
# then edit .env with a text editor and fill in your real values
.gitignore
.env
Changed .env after the stack is already running? A plain docker compose restart grafana is not enough — Grafana's container keeps whatever environment it was originally created with. Use docker compose up -d --force-recreate grafana to actually pick up new values.

Who receives the alerts

This file controls where alert emails go. The only change needed is the placeholder address:

grafana/provisioning/alerting/contactpoints.yaml
apiVersion: 1

contactPoints:
  - orgId: 1
    name: idako-email
    receivers:
      - uid: idako-email-receiver
        type: email
        settings:
          addresses: you@example.com
          singleEmail: true

Replace you@example.com with your real recipient — a comma-separated list works if more than one person should be notified.

Routing — send everything to that one address

This tells Grafana to route every alert to the contact point above — nothing to change here:

grafana/provisioning/alerting/policies.yaml
apiVersion: 1

policies:
  - orgId: 1
    receiver: idako-email
    group_by: ["alertname"]

What triggers an alert

Six conditions, one per subsystem plus two data-quality checks. Every rule queries Prometheus directly and routes through the contact point above via the default policy:

grafana/provisioning/alerting/rules.yaml
apiVersion: 1

groups:
  - orgId: 1
    name: idako-alerts
    folder: Idako
    interval: 1m
    rules:
      - uid: idako-instance-not-ok
        title: Idako instance is not OK
        condition: C
        for: 2m
        labels:
          severity: critical
        annotations:
          summary: "Idako instance is not reachable (Prometheus scrape of the /health endpoint is failing)"
        noDataState: Alerting
        execErrState: Alerting
        data:
          - refId: A
            relativeTimeRange: { from: 300, to: 0 }
            datasourceUid: prometheus
            model:
              expr: up{job="idako"}
              instant: true
              intervalMs: 1000
              maxDataPoints: 43200
              refId: A
          - refId: C
            datasourceUid: "__expr__"
            model:
              type: threshold
              expression: A
              conditions:
                - evaluator:
                    type: lt
                    params: [1]
              refId: C

      - uid: idako-buffer-not-ok
        title: Local Buffer is down
        condition: C
        for: 2m
        labels:
          severity: critical
        annotations:
          summary: "Idako's local buffer subsystem is not running (idako_buffer_up is 0)"
        noDataState: Alerting
        execErrState: Alerting
        data:
          - refId: A
            relativeTimeRange: { from: 300, to: 0 }
            datasourceUid: prometheus
            model:
              expr: idako_buffer_up
              instant: true
              intervalMs: 1000
              maxDataPoints: 43200
              refId: A
          - refId: C
            datasourceUid: "__expr__"
            model:
              type: threshold
              expression: A
              conditions:
                - evaluator:
                    type: lt
                    params: [1]
              refId: C

      - uid: idako-tsdb-not-ok
        title: TSDB is down
        condition: C
        for: 2m
        labels:
          severity: critical
        annotations:
          summary: "Idako's connection to the time-series database is not OK (idako_tsdb_up is 0)"
        noDataState: Alerting
        execErrState: Alerting
        data:
          - refId: A
            relativeTimeRange: { from: 300, to: 0 }
            datasourceUid: prometheus
            model:
              expr: idako_tsdb_up
              instant: true
              intervalMs: 1000
              maxDataPoints: 43200
              refId: A
          - refId: C
            datasourceUid: "__expr__"
            model:
              type: threshold
              expression: A
              conditions:
                - evaluator:
                    type: lt
                    params: [1]
              refId: C

      - uid: idako-server-disconnected
        title: OPC UA server disconnected
        condition: C
        for: 2m
        labels:
          severity: warning
        annotations:
          summary: "OPC UA server {{ $labels.server }} ({{ $labels.endpoint }}) is disconnected"
        noDataState: OK
        execErrState: Alerting
        data:
          - refId: A
            relativeTimeRange: { from: 300, to: 0 }
            datasourceUid: prometheus
            model:
              expr: idako_collector_server_up
              instant: true
              intervalMs: 1000
              maxDataPoints: 43200
              refId: A
          - refId: C
            datasourceUid: "__expr__"
            model:
              type: threshold
              expression: A
              conditions:
                - evaluator:
                    type: lt
                    params: [1]
              refId: C

      - uid: idako-bad-variables
        title: Bad variables detected
        condition: C
        for: 2m
        labels:
          severity: warning
        annotations:
          summary: "{{ $values.A }} variable(s) are reporting bad quality"
        noDataState: Alerting
        execErrState: Alerting
        data:
          - refId: A
            relativeTimeRange: { from: 300, to: 0 }
            datasourceUid: prometheus
            model:
              expr: idako_collector_bad_variables
              instant: true
              intervalMs: 1000
              maxDataPoints: 43200
              refId: A
          - refId: C
            datasourceUid: "__expr__"
            model:
              type: threshold
              expression: A
              conditions:
                - evaluator:
                    type: gt
                    params: [0]
              refId: C

      - uid: idako-forwarding-behind-collection
        title: TSDB forwarding is falling behind collection
        condition: D
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: "Forwarding rate is more than 10% slower than the collection rate — the buffer backlog is likely growing"
        noDataState: OK
        execErrState: Alerting
        data:
          - refId: A
            relativeTimeRange: { from: 300, to: 0 }
            datasourceUid: prometheus
            model:
              expr: idako_collector_rate
              instant: true
              intervalMs: 1000
              maxDataPoints: 43200
              refId: A
          - refId: B
            relativeTimeRange: { from: 300, to: 0 }
            datasourceUid: prometheus
            model:
              expr: idako_tsdb_values_forwarded_rate
              instant: true
              intervalMs: 1000
              maxDataPoints: 43200
              refId: B
          - refId: C
            datasourceUid: "__expr__"
            model:
              type: math
              expression: "($A - $B) / $A"
              refId: C
          - refId: D
            datasourceUid: "__expr__"
            model:
              type: threshold
              expression: C
              conditions:
                - evaluator:
                    type: gt
                    params: [0.1]
              refId: D
RuleFires whenSeverity
Idako instance is not OKup{job="idako"} is 0 for 2mcritical
Local Buffer is downidako_buffer_up is 0 for 2mcritical
TSDB is downidako_tsdb_up is 0 for 2mcritical
OPC UA server disconnectedidako_collector_server_up is 0 for 2m — one alert per server, named in the emailwarning
Bad variables detectedidako_collector_bad_variables > 0 for 2mwarning
TSDB forwarding is falling behind collectionforwarding rate < 90% of collection rate for 5mwarning
Why up{job="idako"} and not a custom Idako metric? This is Prometheus's own, built-in signal for "could I reach this target at all" — it gets a fresh value on every single scrape attempt, success or failure, so it detects a fully unreachable instance within one scrape interval. A metric Idako itself produces (like idako_up) simply stops updating when Idako is unreachable, which is a much slower and less reliable way to notice a total outage.
Both firing and resolved notifications are sent — that's Grafana's default (a per-contact-point "Disable resolved message" option turns the second one off, if you'd rather only hear about new problems). Firing waits out the rule's for duration to avoid paging on a blip; resolved notifications go out on the next evaluation after the condition clears, no equivalent delay.
5

The Docker Compose file

docker-compose.yml wires everything together: Prometheus reads its config from step 2, Grafana reads its provisioning from steps 3–4 and its SMTP settings from .env, and both get a named volume so data survives a restart. Nothing to change here — it's already set up.

docker-compose.yml
services:
  prometheus:
    image: prom/prometheus:latest
    container_name: idako-prometheus
    restart: unless-stopped
    volumes:
      - ./prometheus/prometheus.yml:/etc/prometheus/prometheus.yml:ro
      - prometheus-data:/prometheus
    ports:
      - "9090:9090"

  grafana:
    image: grafana/grafana:latest
    container_name: idako-grafana
    restart: unless-stopped
    depends_on:
      - prometheus
    volumes:
      - ./grafana/provisioning:/etc/grafana/provisioning:ro
      - grafana-data:/var/lib/grafana
    ports:
      - "3000:3000"
    env_file:
      - .env

volumes:
  prometheus-data:
  grafana-data:
.env must exist before this will start. env_file: - .env means Docker Compose refuses to start the grafana service if that file is missing — make sure step 4's cp .env-example .env happened first.
6

Start the stack

From inside the idako-monitoring folder:

shell
docker compose up -d

Confirm both containers are running:

shell
docker compose ps

Then confirm Prometheus can actually reach Idako — open http://localhost:9090/targets in a browser. The idako target should show State: UP. If it shows DOWN, the error message next to it almost always names the problem — usually the host/port in step 2, or a firewall between the Docker host and Idako.

7

Open the dashboard

Go to http://localhost:3000 to sign in.

Default credentials: admin / admin. Grafana ships with this login out of the box and prompts you to set a real password the moment you sign in — do that immediately, especially if port 3000 is reachable from beyond your own machine.

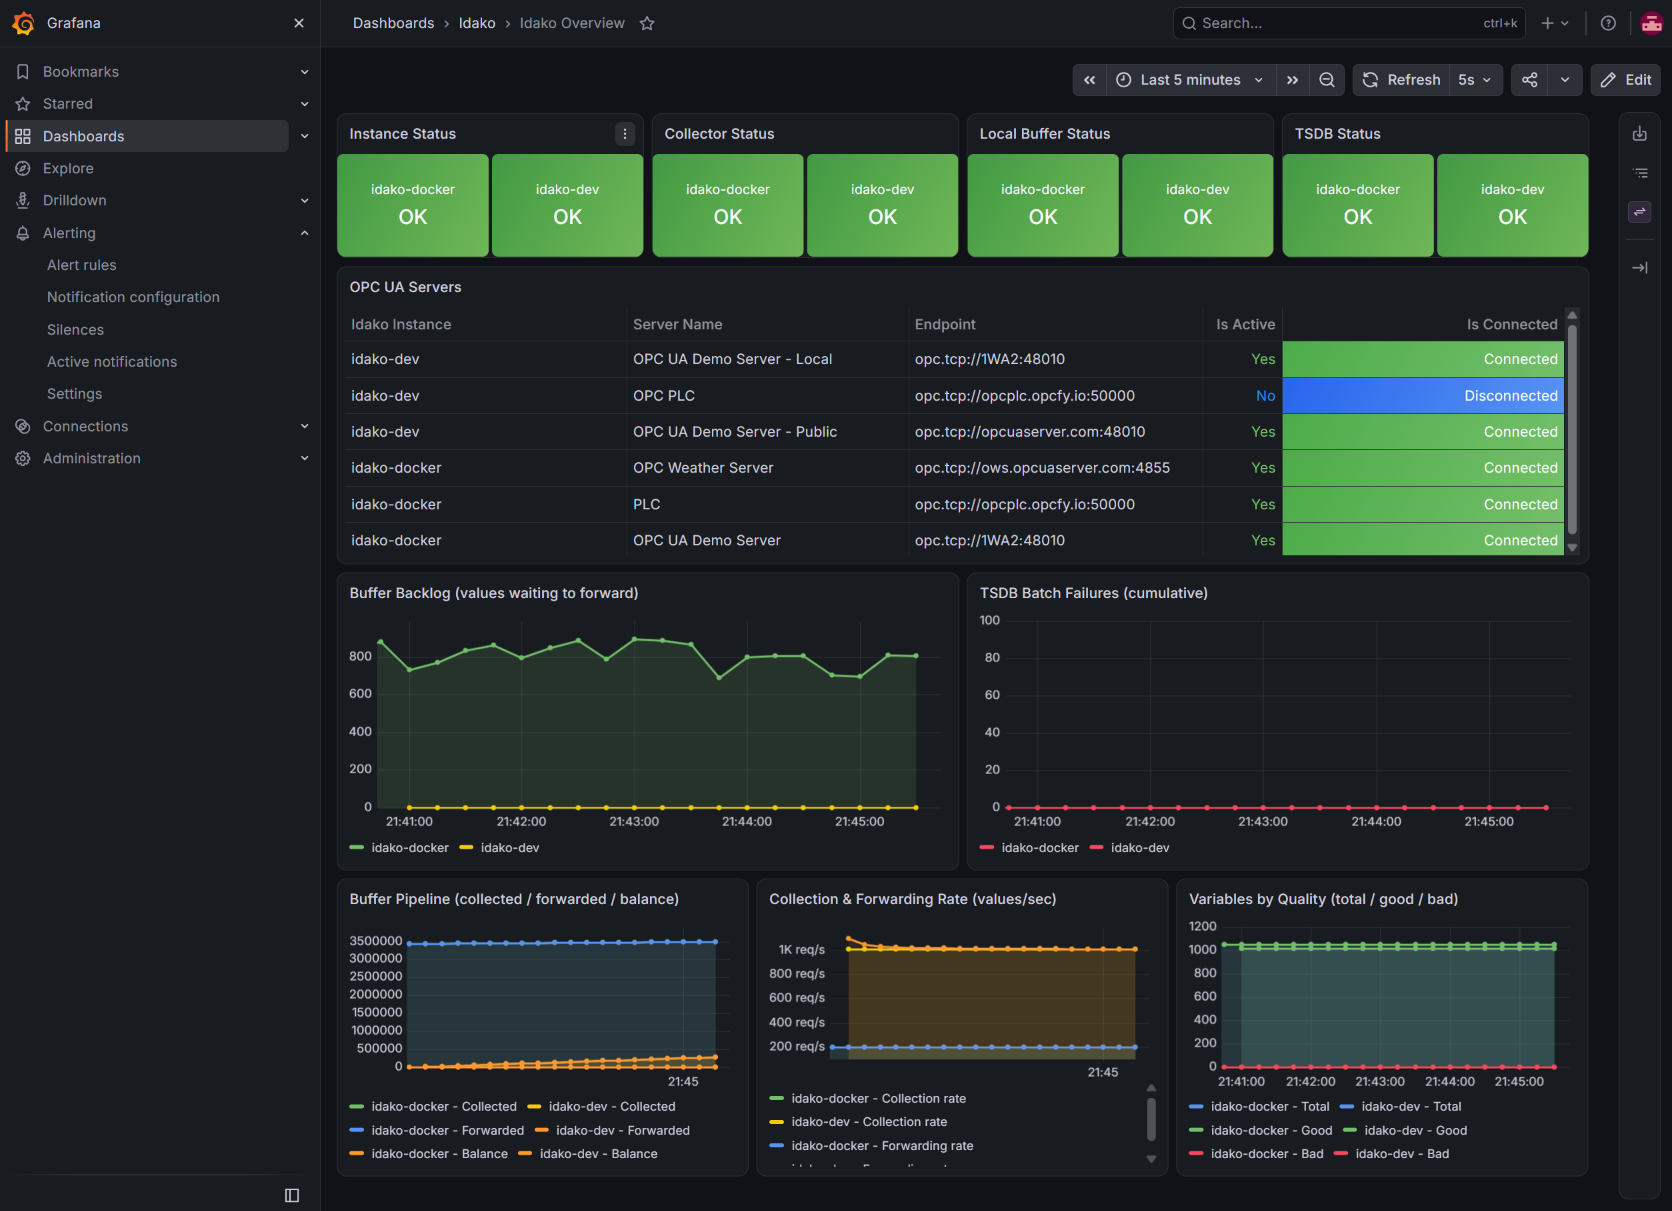
In the left menu, go to Dashboards — the Idako folder and the Idako Overview dashboard inside it were created automatically by the files from step 3. Open it — it should look like this:

The Idako Overview dashboard in Grafana: four green OK status tiles, a connected-server count, and six live charts showing buffer, tsdb, and variable-quality trends.
The Idako Overview dashboard, running against a healthy instance.
You should see green OK tiles for Instance, Collector, Local Buffer, and TSDB Status, a count of connected servers, and five live charts. If everything reads zero or empty, double-check the target is UP on the Prometheus targets page from step 6 first — an unreachable target is the most common cause.
Beyond one instance

Monitoring more than one Idako instance

Add one more entry to targets in prometheus/prometheus.yml — no changes needed anywhere else, including the dashboard and alert rules, since they already aggregate across whatever Prometheus is scraping:

prometheus/prometheus.yml (excerpt)
    static_configs:
      - targets:
          - "idako-host-1:4880"
          - "idako-host-2:4880"

Restart Prometheus to pick up the change: docker compose restart prometheus.

Before you trust it

Verifying the alerts actually work

A clean startup only proves Grafana accepted the SMTP settings, not that mail actually gets delivered. Two checks worth doing once, right after setup:

  • Send a test email — in Grafana, go to Alerting → Contact points, open idako-email, and use Test. This confirms your SMTP credentials and relay are correct in isolation, before any real alert depends on them.
  • Trigger a real one — stop Idako (or block the port) and wait a few minutes. "Idako instance is not OK" should reach Alerting → Active notifications within about 2–3 minutes, and land in your inbox shortly after. Bring Idako back and you should get a second, resolved email on the next evaluation.
SMTP authentication failing? The most common cause after a config change isn't a wrong password — it's a stale container. Confirm what's actually loaded with docker exec idako-grafana printenv | grep GF_SMTP and compare against your current .env; if they differ, that's the --force-recreate step from earlier being skipped, not a credentials problem.
Next steps

Where to go from here

More alert conditionsAdd another rule to the same rules.yaml group — e.g. a warning specifically for a growing idako_buffer_values_balance, before it turns into lost data.
Route by severityAdd a second contact point (e.g. a chat webhook) and a policy that matches on the severity: critical label already set on three of the six rules, so only the urgent ones page immediately.
Distinguish "down" from "metrics are broken"A blackbox_exporter container probing plain GET /health catches the narrower case where Idako is healthy but its Prometheus output specifically is malformed — up{job="idako"} alone can't tell those apart.
Keep history longer than Prometheus's defaultPrometheus's local storage is fine for weeks of data; for longer retention, point it at a remote-write target instead of changing anything on the Idako side.
Prefer a lighter agent to a separate stack?The Idako + NetData guide reads this same /health endpoint with two stock NetData collectors — nothing new to run if you already have a NetData agent watching this host.
See exactly what Idako reportsThe full field-by-field reference for /health, including every metric this dashboard and these alerts are built from.
This stack talks to Idako over plain HTTP on its health port — no credentials, no changes to Idako required. Everything here runs on infrastructure you control.